Section outline
-
-
Seaborn also allows you to create heatmaps using heatmap().
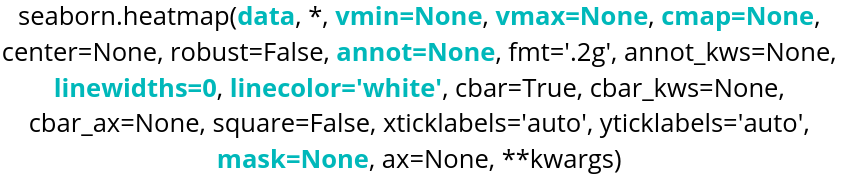
Parameter name Explanations Required type Example data Table you are planning to use DataFrame, Series, dict, array, or list of arrays data=table cmap Heatmap colors: either a Matplotlib color palette or a custom palette. String corresponding to a color palette or color_palette of Seaborn cmap="viridis" or cmap=sns.color_palette("light:blue", as_cmap=True) annot Variable that determines whether the cell values are displayed. Boolean annot=True, False by default vmin Minimum value considered for the colormap. Float value vmin=30.6 vmax Maximum value considered for the colormap. Float value vmax=42 linecolor Variable used to choose the color of the lines between cells. String corresponding to a color linecolor="blue" linewidths Variable controlling the thickness of the lines between cells. Float value linewidths=0.2 or linewidths=10 mask Variable used to control the values displayed in the heatmap. Boolean table with the same format as data mask=tableau_mask
Here is an example of code:
We use pivot to format the data in the desired order:
- index specifies the variable for the y-axis.
- columns specifies the variable for the x-axis.
- values must be a numerical variable, and this is what the heatmap will use to determine the cell colors.
With the vmin and vmax parameters, we can define the range of values over which the heatmap will be applied. We also have graphical options such as linecolor and linewidths to customize the lines between cells. annot displays the values in each cell of the heatmap.
If you need to perform clustering on a heatmap, you can use Seaborn's clustermap(). Note that this function requires SciPy, so you will need to install it in the environment you are working in. If you are using Google Colab, this will not be necessary, as you can import it directly.
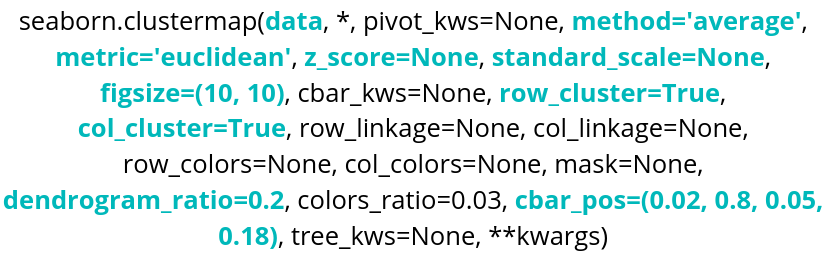
Parameter name Explanations Required type Example data Table you are planning to use DataFrame, Series, dict, array, or list of arrays data=table method SciPy method for clustering String corresponding to a SciPy method method="centroid" metric SciPy metric for clustering String corresponding to a SciPy metric metric="jaccard" z_score Variable used to standardize the data 0 for rows, 1 for columns z_score=0 standard_scale Variable used to normalize the data 0 for rows, 1 for columns standard_scale=1 row_cluster,
col_clusterVariables used to choose the clustering axes Boolean row_cluster=False figsize Variable controlling the size of the figure tuple(width,height) figsize=(4,4) dendrogram_ratio Variable controlling the size ratio of the dendrograms tuple(row ratio, column ratio) dendrogram_ratio=(0.2,0.1) cbar_pos Variable controlling the position of the color bar tuple(left,bottom,width,height) cbar_pos=(0,0.1,0.05,0.6)
Here is an example of code:
We remove the extra variable using pop() to perform the clustering. In this case, the variable is
"species", which we will reuse later.The dendrograms are the trees displayed on the sides of the clustermap that represent the different clusters formed.
Now, let's explore some of the different parameters:
row_cluster groups the rows according to their similarity in order to reveal clusters. dendrogram_ratio controls the size of the dendrograms; the first value corresponds to the one on the left and the second to the one at the top. row_colors adds a color next to the rows. Here, using the previous lines, the species corresponding to each row are displayed.
metric allows you to choose the similarity distance used, while method specifies the algorithm used to perform the clustering. Setting z_score to 1 indicates that the data is normalized across the rows. cbar_pos allows you to choose the position of the color bar. annot displays the values in each cell. figsize controls the size of the figure.
-